



Database Synchronization Tools: How to Choose
Compare database replication, CDC, managed application sync, and scheduled pipelines using write direction, record identity, recovery, and operating needs.
- Author
- Ruben Burdin · Founder & CEO
- Published
- Updated
- Read time
- 5 min read
Choose the tool category before comparing products
Database synchronization tools solve different problems. A database replica, a stream of change events, an analytics load, and a CRM write-back integration can all move rows, but they have different correctness contracts. Start with the destination and who is allowed to edit the data.
If an application only needs a read model, one-way replication or ingestion may be sufficient. If people edit related records in a CRM and your database application, the integration also needs cross-system identity, field ownership, destination validation, and recovery. Two-way direction alone does not establish those behaviors.
Use the database integration overview for supported product paths and the evaluation worksheet to compare your shortlisted approaches.
Compare four practical approaches
| Approach | Example | Primary fit | Work still required |
|---|---|---|---|
| Database-native replication | PostgreSQL logical replication | Publishing selected database changes to subscribers | Replica identity, privileges, conflicts, schema and operations |
| Change data capture framework | Debezium PostgreSQL connector | Producing database change events for downstream consumers | Consumer behavior, destination delivery, recovery and business policies |
| Managed application synchronization | Stacksync | Connecting supported database and business application objects | Mapping, field ownership, access and acceptance tests |
| Scheduled extract and load | A controlled batch pipeline | Reporting or periodic refresh with acceptable delay | Schedule, incremental boundary, reconciliation and stale-data handling |
These are method examples, not a ranked benchmark. PostgreSQL’s logical replication documentation covers publication, subscription, replica identity, conflicts, and restrictions. Debezium’s PostgreSQL documentation covers its snapshot and streaming change capture. Review the exact versions and deployment constraints of any tool you select.
A captured event stream does not itself define what a Salesforce field may overwrite or what a NetSuite transaction should do. Conversely, a managed application connector should be evaluated against the selected object and permissions rather than treated as a substitute for every database replication requirement.
Preserve database keys and application identity
A local primary key identifies a database row. An external record ID identifies the corresponding application entity. They may serve different purposes. Keep the pairing explicit, add the appropriate uniqueness rules, and decide what a merge or deletion means for references to that entity.
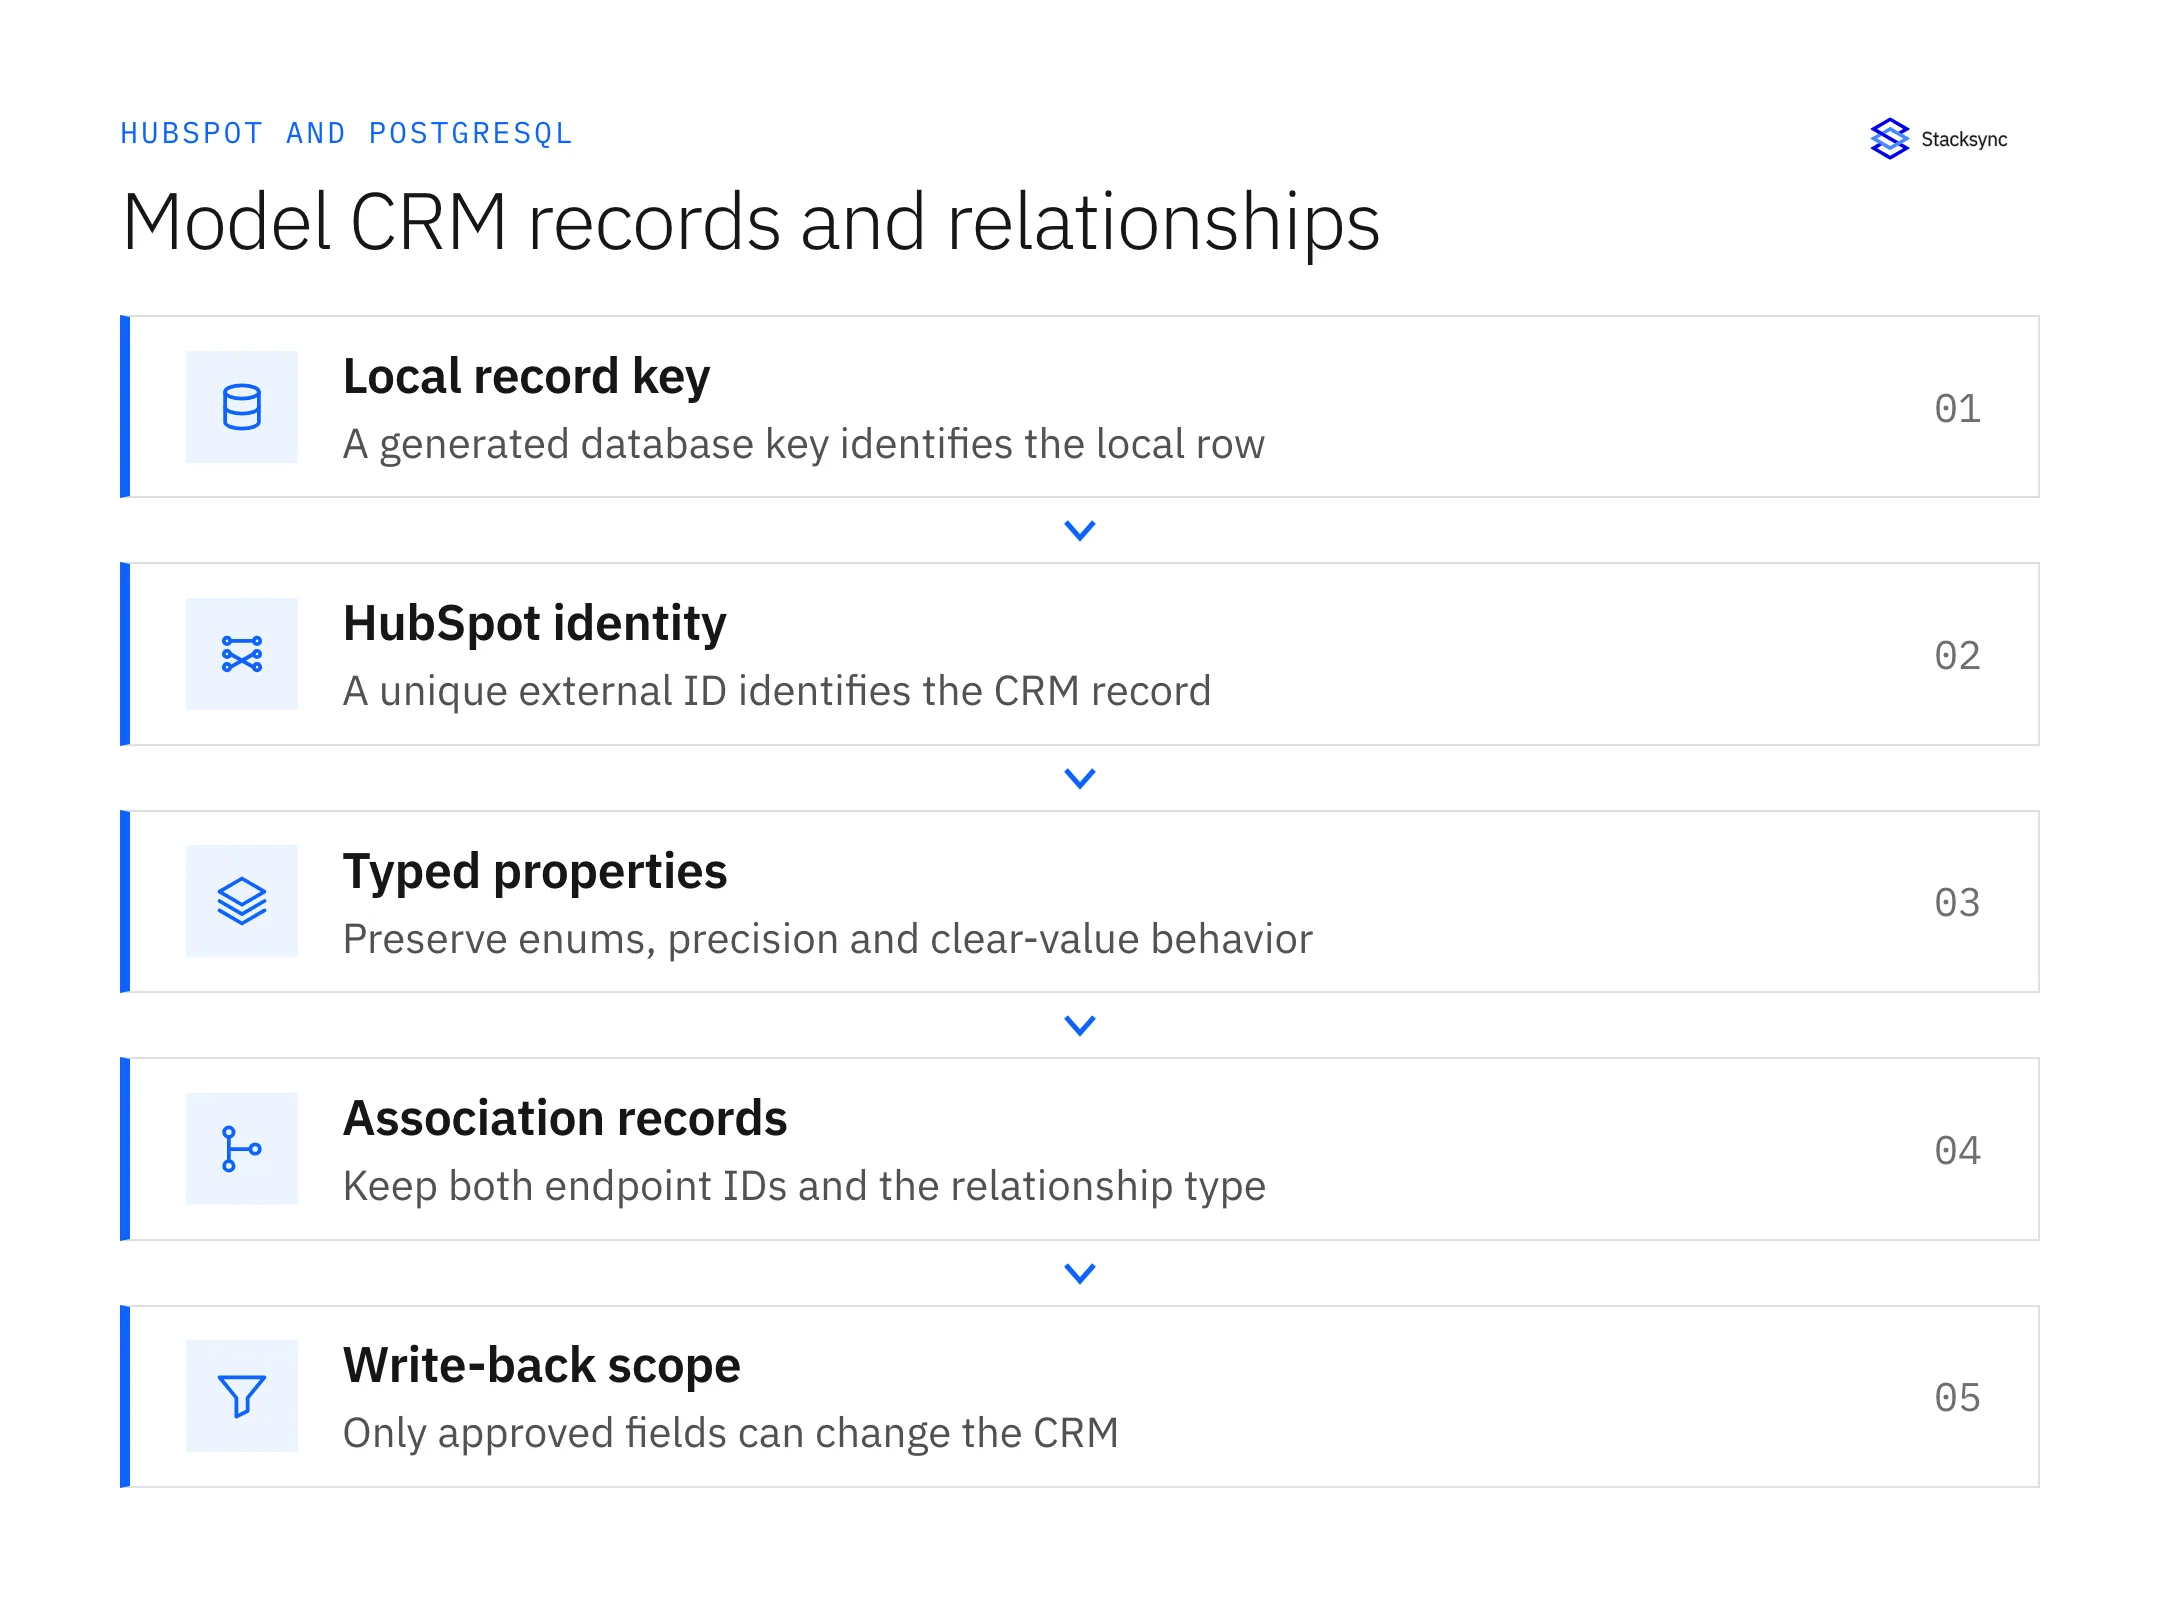
For Stacksync’s PostgreSQL connector, the current guide specifies a single automatically generated primary key on synced tables and documents the required permissions. Verify these requirements on the actual database host before planning an existing composite-key table as a direct fit.
Type compatibility also needs a test. Check timestamps and timezones, decimal precision, enums, nulls, generated fields, and relationships. A successful initial string value does not prove that every later value can be written to the destination.
Test the return path separately from ingestion
A database copy that is useful for queries may still be unsuitable as an unrestricted editing surface. Mark application-owned fields as read-only in the database workflow where appropriate. Allow return writes only when the business and connector support them.
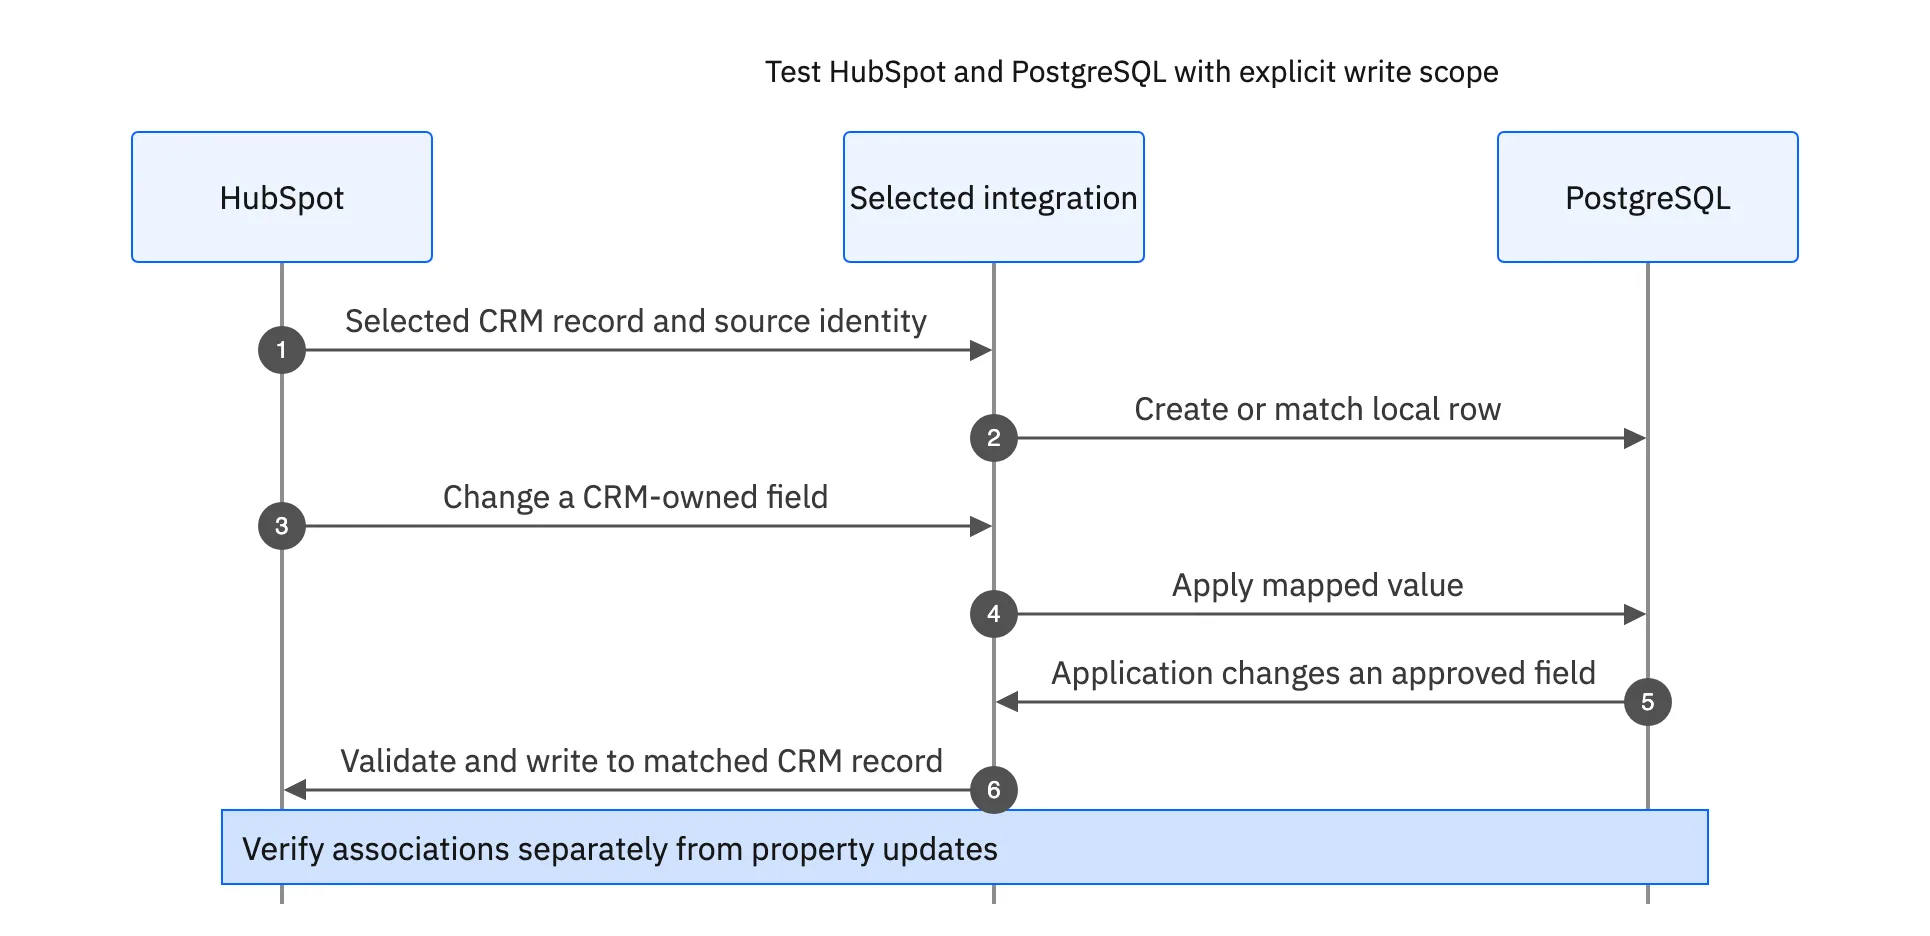
Use the HubSpot–PostgreSQL guide for a concrete record and association example. The key acceptance case is not merely “the SQL update succeeded.” Inspect the destination record, any validation errors, and the workflows triggered by that update.
If both applications edit the same value, document the outcome before introducing concurrency. If they edit different values that share a business constraint, validate the combined record too. The mapping workbook records that ownership contract.

Measure freshness, recovery, and correctness
| Measure | What it reveals | How to avoid a misleading result |
|---|---|---|
| End-to-end lag | Age of usable destination data | Start the clock at the business edit |
| Oldest unresolved record | Long-lived failures hidden by averages | Inspect exceptions separately from healthy traffic |
| Backlog drain rate | Ability to recover after an outage | Include new incoming traffic during the test |
| Identity reconciliation | Missing and duplicate entities | Compare stable IDs, not only total counts |
| Value and relationship checks | Whether the intended business state agrees | Use selected critical fields and dependencies |
Do not select a universal millisecond target for every workload. A reporting extract and an operational order handoff can tolerate different delays. Establish the target from the business action, then test representative volume and concurrent API consumers.
Observe the failure path as well as normal throughput. A constraint violation, expired credential, or invalid destination value should become an actionable issue. An empty queue alone does not establish that every selected record is correct.
Build a shortlist with explicit ownership
- 01Write down the source, destination, objects, expected volume, and required directions.
- 02Identify the approved editor for each synchronized field.
- 03Check connector prerequisites, hosting limits, and supported write operations.
- 04Run initial-load, duplicate, invalid-value, concurrent-edit, and outage cases.
- 05Estimate service costs together with engineering, monitoring, and incident response.
- 06Record the accepted limitations and name the operating owner.
Use the production-readiness checklist and recovery runbook before expanding writes. For a Stacksync review, bring your database schema and application pair with one difficult key or relationship so the discussion can resolve an actual implementation constraint.
FAQ
Frequently asked questions



Explore these integrations and topics
- connectorPostgreSQL integrations
- platformTwo-way sync
- platformDatabase synchronization
- Two-way sync guidesUnderstand two-way sync, record matching, field ownership, and production readiness.
- Database synchronization guidesWork through database change capture, application writes, and reliable record reconciliation.
Related articles