




ETL vs Reverse ETL vs Two-Way Sync: Choose the Data Flow
Compare ETL, ELT, reverse ETL, and bidirectional sync by direction, field ownership, freshness, and recovery. Plan analytical and operational data flows.
- Author
- Ruben Burdin · Founder & CEO
- Published
- Updated
- Read time
- 5 min read
Choose by where data is prepared and who edits it
ETL moves extracted data through a transformation step before loading it into a destination. ELT loads it first and transforms it there. Reverse ETL sends prepared data, often from a warehouse, into operational applications. Two-way sync coordinates approved edits in both directions between systems.
These terms describe related but different design choices. Reverse ETL is not automatically bidirectional, and ETL is not limited to a nightly schedule. A business can use ingestion for analytics, reverse ETL for calculated attributes, and a separate two-way integration for jointly edited operational records.
Start with a concrete outcome: build a report, publish a customer segment, or keep a customer record editable in two applications. That outcome determines the direction, ownership rules, and freshness target.
Compare the contracts, not just the arrows
| Pattern | Data flow | Typical responsibility | Key test |
|---|---|---|---|
| ETL | Extract, transform, then load | Prepare source data before it enters the destination | Transformation produces the intended records |
| ELT | Extract, load, then transform | Model data inside the destination | Loaded data and model refresh are both complete |
| Reverse ETL | Prepared dataset to a business application | Publish selected derived values | The destination entity and writable fields are correct |
| Two-way sync | Approved changes travel in both directions | Coordinate multiple editing surfaces | Competing writes follow the ownership policy |
The timing depends on the implementation. AWS Glue documentation is one example of a service supporting several data integration approaches, including ETL, ELT, and streaming. Evaluate how a particular job captures, processes, and delivers changes rather than assigning speed from its category name.
Example: publish a customer health score
Suppose a warehouse combines product usage, support history, and billing records into a customer health score. A reverse ETL job writes the score and its calculation timestamp to the CRM. The warehouse owns those derived fields; sales continues to own account notes and the sales process.
The score’s freshness depends on more than the final delivery job. Source ingestion must run, the model must recompute, and the destination update must succeed. A one-minute export interval cannot make a score current if its input dataset is a day old.
| Stage | Owner | Evidence |
|---|---|---|
| Source ingestion | Data platform team | Latest included source change or partition |
| Score calculation | Analytics owner | Model version and calculation time |
| CRM matching | Integration owner | Stable customer ID and destination record |
| Score delivery | Integration owner | Accepted destination value and timestamp |
| Business use | Sales operations | Documented behavior when the score is stale |
This is an illustrative design, not a customer result. Define how unknown customers, missing scores, and changes to the model behave. An empty result set should not accidentally clear every CRM score without an agreed policy.
When you need a two-way operational path
Add a return path when a second system has a legitimate editing responsibility. For example, an internal application may let an operations team correct a contact value that should return to the CRM. That flow needs stable identity, permitted properties, validation, and conflict behavior.
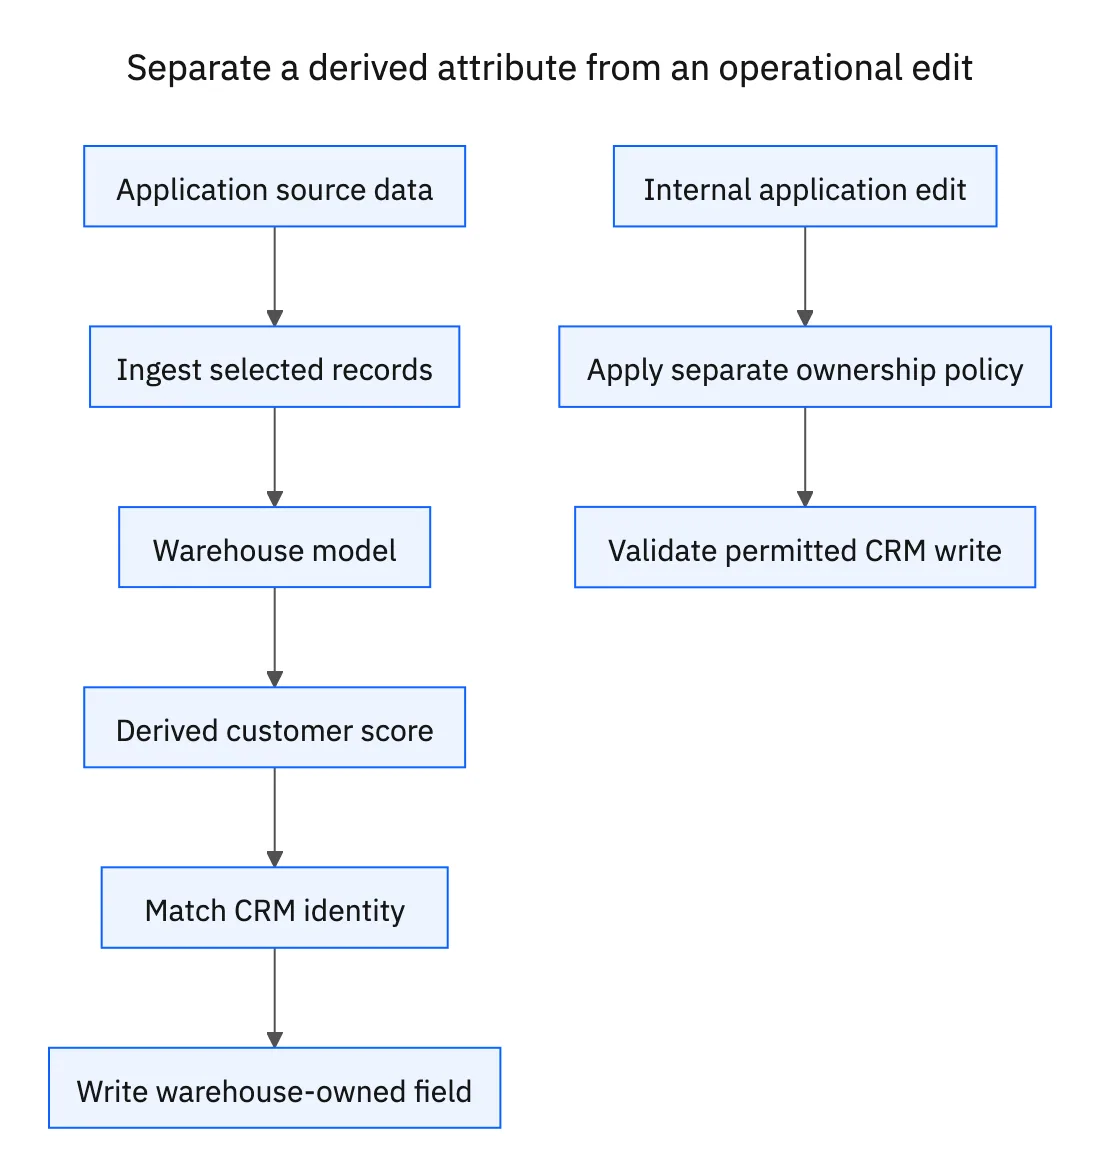
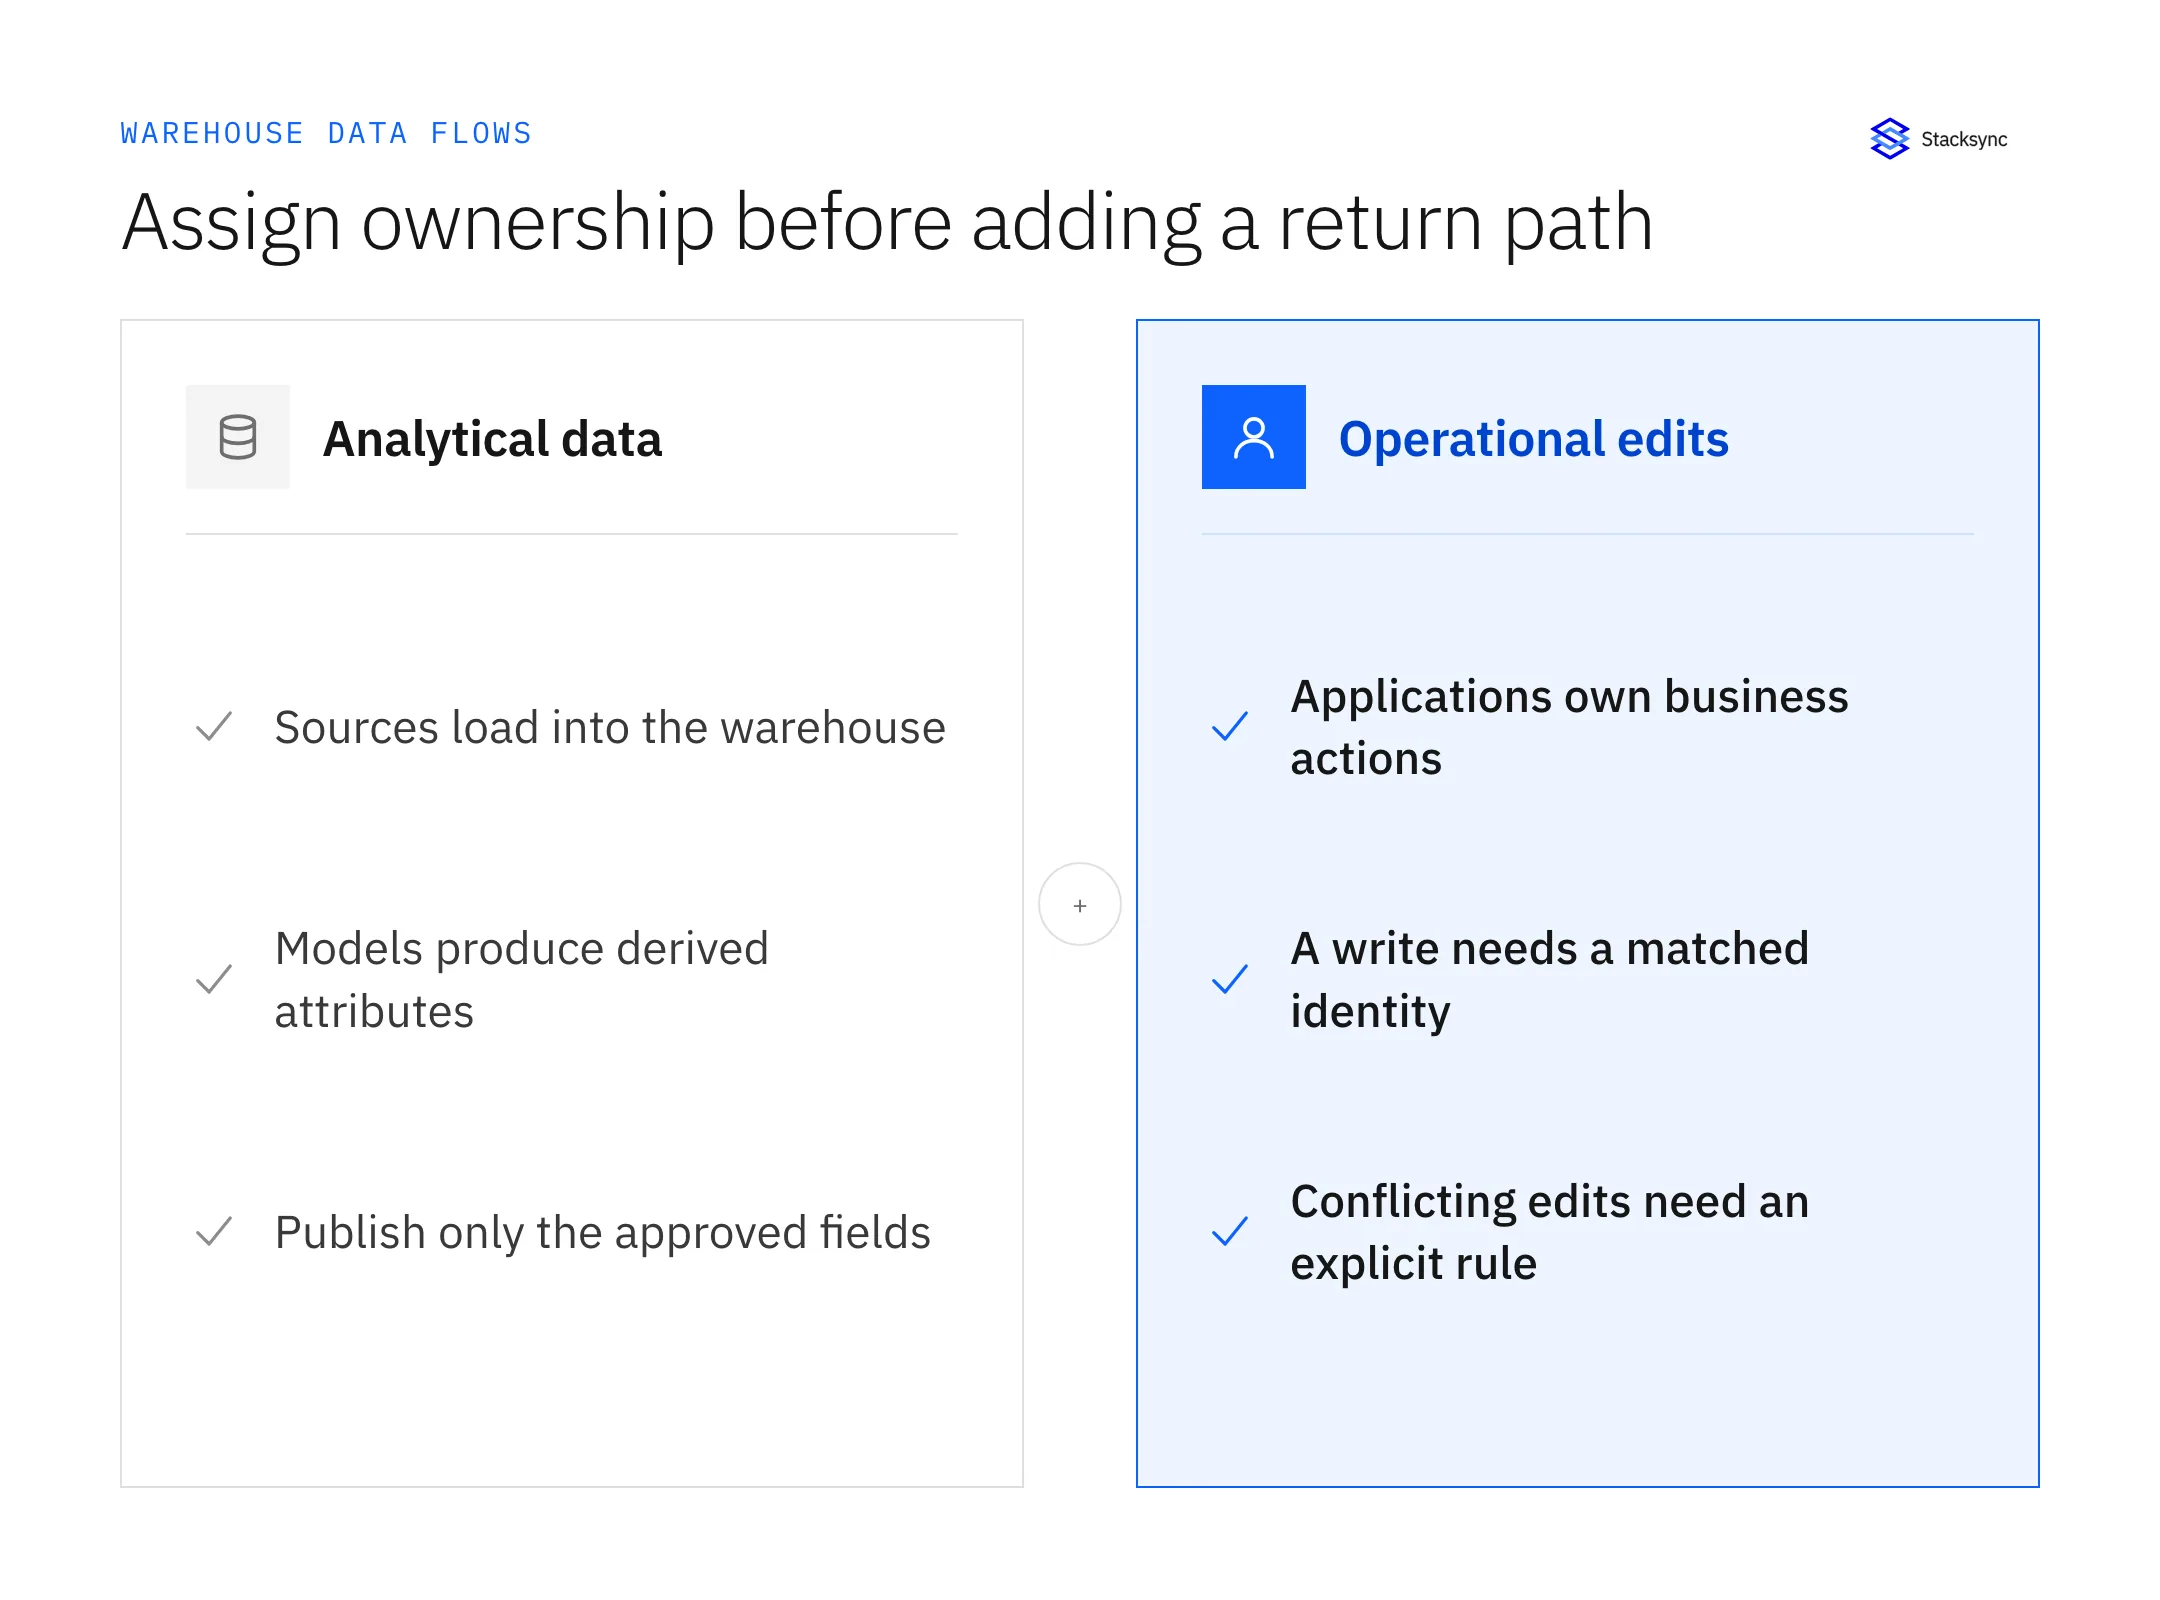
Do not write a derived warehouse value to a CRM field that users expect to own unless the overwrite rule is explicit. If a person must override the calculated result, consider separate calculated and override fields with a documented effective-value rule. The design should make it clear which value is authoritative.
The field mapping workbook captures ownership and null behavior for each path. The HubSpot–PostgreSQL guide provides a concrete example of operational database write-back that should be evaluated separately from analytics ingestion.
Verify the actual connector and destination
Check database or warehouse permissions, key requirements, selected tables, and writable application fields. A connector appearing in a catalog establishes a starting point; it does not prove every object, transformation, or write direction needed by a workflow.
For Stacksync, begin with the warehouse integration overview and the specific Snowflake connector documentation or other relevant connector guide. Validate the live connection’s capabilities before relying on operational write-back from a warehouse.
A useful evaluation includes a normal update, a missing match, an invalid destination value, and a repeated delivery. Also test what happens when a warehouse model drops a row or changes its customer key. Reconciliation must distinguish an intentional exclusion from a lost record.

Define what recovery must reproduce
A current customer score may only require the latest calculated value after an outage. A workflow triggered by every status transition may require event history. Decide whether recovery should restore present state or process intermediate changes, then test that behavior explicitly.
The retry and replay guide explains the distinction. Stacksync’s documented Issues dashboard retry reads current source values; it should not be described as a universal historical-event replay mechanism. Keep downstream actions in the acceptance scope.
Set alerts for stale model output, rejected writes, and missing entity matches. A green extraction job cannot establish that an account manager sees the correct CRM value. Measure the complete path from the relevant source change to the field used by the business.
Choose a design and record the decision
- 01For reporting, first evaluate ingestion and transformation into the analytical destination.
- 02For publishing derived attributes, evaluate a one-way activation path with explicit field ownership.
- 03For jointly edited operational records, evaluate bidirectional behavior and conflict handling.
- 04For workflows requiring every transition, evaluate retained events and delivery semantics.
- 05Compare options with the same data volume, objects, freshness target, and recovery cases.
Use the integration evaluation worksheet and production checklist to preserve the evidence. If Stacksync is on the shortlist, bring the full data path and field ownership rules to an integration review so the discussion covers the business outcome as well as the connection.
FAQ
Frequently asked questions

Explore these integrations and topics
- platformIntegration architecture
- platformWarehouse data flows
- Two-way sync guidesUnderstand two-way sync, record matching, field ownership, and production readiness.
- Warehouse data flows guidesChoose between ingestion, reverse ETL, and operational write-back for warehouse data.
- Integration architecture guidesEvaluate integration methods and design for conflicts, retries, failures, and changing schemas.
Related articles