





Eliminating Duplicate Records When You Sync CRM Systems: Best Practices for Clean Data
Eliminating duplicates when you sync CRM systems isn't a one-time project but an ongoing process. By implementing the preventive measures, detection methods, and resolution techniques outlined in this guide, you'll maintain clean customer data that enables accurate reporting, efficient operations, and superior customer experiences.
- Author
- Ruben Burdin · Founder & CEO
- Published
- Updated
- Read time
- 10 min read
Duplicate records create serious business problems. When you sync CRM systems without proper deduplication controls, these issues multiply rapidly across your technology stack, leading to:
- Inaccurate reporting and forecasting
- Wasted time from sales teams contacting the same prospect multiple times
- Inflated marketing costs through duplicate communications
- Poor customer experience when their history isn't properly consolidated
- Skewed analytics that distort business decisions
This guide provides practical methods to prevent, identify, and eliminate duplicates when synchronizing CRM data across systems.
Why Duplicates Occur During CRM Synchronization
Understanding the root causes of duplication helps prevent future occurrences:
1. Matching Field Inconsistencies
When you sync CRM platforms using different unique identifiers, duplicates emerge. Common scenarios include:
- System A uses email as the primary identifier while System B uses phone number
- Records with slight variations in key fields (e.g., "123 Main St" vs "123 Main Street")
- Case sensitivity differences in matching fields ("john.smith@example.com" vs "John.Smith@example.com")
2. Bidirectional Sync Conflicts
Two-way synchronization often creates duplicates when:
- The same record is created independently in both systems before initial sync
- Conflict resolution logic fails to properly merge concurrent changes
- Each system generates its own unique ID, causing record duplication
3. Data Transformation Issues
Field mapping problems during synchronization lead to duplicates through:
- Truncated fields that no longer match (e.g., "International Business Machines" vs "International Business Machin")
- Format inconsistencies in phone numbers, dates, or addresses
- Character encoding issues with international data
4. Sync Timing Problems
The sequence and timing of synchronization processes create duplicates when:
- Batch processes run concurrently without proper locking mechanisms
- Initial load and incremental sync logic conflicts
- System outages interrupt synchronization mid-process
Prevention: Best Practices Before You Sync CRM Systems
Preventing duplicates is far more efficient than cleaning them afterward. Implement these practices before synchronizing:
1. Establish Consistent Unique Identifiers
Create a reliable method for uniquely identifying records across systems:
- Define a single source of truth for each record type
- Use globally unique identifiers (GUIDs) where possible
- Implement cross-system ID mapping tables when native IDs can't be shared
- Never rely solely on name fields for matching
Example matching hierarchy for contact records:
- 01External ID field (if available and populated)
- 02Email address (normalized to lowercase)
- 03Phone + Last Name + Zip (with phone normalized to E.164 format)
2. Normalize Data Before Syncing
Standardize data formats to improve match rates:
- Convert all emails to lowercase
- Standardize phone numbers to E.164 format (e.g., +12025550123)
- Normalize addresses using postal standards
- Remove special characters, excess spaces, and common abbreviations
Example SQL normalization for duplicate detection
SELECT
LOWER(email) as normalized_email,
REGEXP_REPLACE(phone, '[^0-9]', '') as normalized_phone,
UPPER(TRIM(company_name)) as normalized_company
FROM contacts
3. Implement Pre-Sync Deduplication
Clean individual systems before connecting them:
- Run deduplication processes within each system first
- Resolve obvious duplicates using the system's native tools
- Establish merging rules before syncing begins
- Document which fields should survive during merges
4. Design Proper Conflict Resolution Rules
Create explicit rules for handling potential conflicts:
- Determine which system is authoritative for each field
- Establish time-based rules (most recent update wins)
- Create field-level survivorship rules (e.g., longest value wins for description fields)
- Define process for handling true conflicts requiring manual review
Detection: Identifying Duplicates Across Synchronized Systems
Even with prevention measures, duplicates will occur. Implement these detection methods:
1. Fuzzy Matching Algorithms
Go beyond exact matching with algorithms that account for common variations:
- Levenshtein distance for detecting small differences in text
- Phonetic matching (Soundex, Metaphone) for name variations
- N-gram fingerprinting for detecting word order differences
- Jaro-Winkler distance for detecting transposed characters
Use fuzzy similarity to retrieve candidates for review. Calibrate any threshold against labeled examples from your own records, including different people with similar names and shared contact details. No universal score establishes that two contacts are the same person.
2. Composite Key Matching
Choose evidence appropriate to the record type. For person-level contact matching, use these checks:
- A persistent person identifier or a previously reviewed cross-system contact link
- Verified person-specific email with corroborating identity evidence, allowing for shared or reassigned addresses
- Name and phone evidence reviewed together with their scope and history
- Company and domain as account context only, never sufficient evidence that two employees are one person
Do not merge contacts from a shared email domain or company name. Those attributes can identify a business, but every employee may share them. Keep separate people separate and send ambiguous matches to review before moving activities, permissions, consent, or order history.
3. Progressive Field Relaxation
Implement a tiered matching approach:
- 01Start with strict criteria requiring all fields to match exactly
- 02Broaden candidate search when a strict match is absent, while retaining the same evidence requirement for a merge
- 03Introduce fuzzy matching on specific fields only when needed
A broader search may find more candidates, but it does not authorize a merge. Measure false matches and missed matches separately before changing any automated decision rule.
4. Automated Scheduled Scanning
Regular duplicate detection should be part of your sync maintenance:
- Run daily scans for duplicates created within the last 24 hours
- Perform weekly scans across full datasets
- Create different scanning rules for different record types
- Generate exception reports for manual review
Resolution: Merging and Eliminating Duplicates
Confirm that the records represent the same person before selecting a surviving record or moving relationships. Use a reviewed merge plan; field completeness or recency alone cannot establish identity.
1. Field-Level Survivorship Rules
Define which version of each field survives during merges:
Illustrative merge-review rules; not a Stacksync configuration format
contact_merge_rules:
first_name: "verified_person_value"
last_name: "source_of_truth" # CRM A is authoritative
email: "verified_current_address"
phone: "verified_person_number" # Preserve shared-number ambiguity
address: "most_recently_verified"
created_date: "earliest" # Keep original creation date
lead_source: "preserve_attribution_history"
description: "review_before_combining"
2. Master Record Selection
Establish criteria for selecting the surviving master record:
- Most recently updated record
- Record with most complete data
- Record from the system of record
- Record with most activity history
Once identity is confirmed, choose the surviving record under the owning CRM’s supported merge process. Review permissions, consent, child-record relationships and external IDs before applying it; do not assume every merge can be reversed.
3. Relationship Preservation
Properly handle child records and relationships during merges:
- Reparent child records to the surviving master record
- Consolidate related activities and notes
- Preserve lookup relationships from other objects
- Maintain references in external systems
4. Audit Trail Maintenance
Document the merge process for future reference:
- Record which records were merged and when
- Preserve key fields from non-surviving records
- Create a rollback capability for incorrect merges
- Maintain a searchable history of merged record IDs
Automation: Tools and Platforms for Duplicate Prevention
Manual processes don't scale. These automation approaches maintain clean data:
1. Native CRM Deduplication Features
Leverage built-in capabilities:
- Salesforce Duplicate Management rules
- HubSpot duplicate management tools
- Microsoft Dynamics duplicate detection rules
- Zoho CRM duplicate detection
Most platforms offer basic duplicate prevention, but typically lack cross-system capabilities.
2. Dedicated Deduplication Software
Specialized tools provide advanced features:
- RingLead
- Cloudingo
- DemandTools
- Insycle
These tools excel at cleaning individual systems but may require custom integration with your sync processes.
3. Integration-Layer Deduplication
Handle duplicates within your integration middleware:
- Custom logic in iPaaS platforms (Workato, Mulesoft, etc.)
- ETL tool transformations with matching capabilities
- Custom code within integration frameworks
This approach works but requires significant configuration and maintenance. See our full Workato alternative comparison for how a purpose-built sync engine avoids this maintenance burden.
4. Stable Identity in the Sync Layer
Use durable source and destination IDs to avoid recreating the same synchronized record after a retry. This operational deduplication is different from deciding whether two existing CRM contacts represent one person.
- Define the cross-system identity before enabling writes.
- Resolve existing duplicate people through the owning CRM’s supported review and merge process.
- Reconcile external references after an approved merge.
- Verify any normalization, merge-preview or approval capability instead of assuming it is included with a connector.
Implementation Guide: Establishing a Clean Data Sync Process
Follow this process to implement effective duplicate prevention:
Step 1: Audit Your Current Duplicate Situation
Before implementing new processes:
- 01Run a duplicate analysis report in each system
- 02Identify the highest-volume duplicate patterns
- 03Quantify the business impact (e.g., number of wasted sales contacts)
- 04Document existing deduplication practices or rules
Step 2: Clean Existing Systems
Before connecting systems:
- 01Deduplicate each system individually using native tools
- 02Start with high-confidence duplicates (exact email matches)
- 03Progress to more sophisticated matching criteria
- 04Document merged record IDs for future reference
Step 3: Implement Preventive Controls
Before your first sync:
- 01Configure matching rules in your sync platform
- 02Test with a sample dataset to validate accuracy
- 03Establish survivorship rules for each field
- 04Create exception handling for ambiguous matches
Step 4: Configure Ongoing Monitoring
After sync implementation:
- 01Set up daily duplicate detection scans
- 02Create alerts for potential duplicates requiring review
- 03Measure duplicate recreations, false merges and unresolved candidates against a reviewed baseline
- 04Implement regular data quality reports
Illustrative Review: Similar Contacts at One Company
Consider a hypothetical advisory firm whose CRM has two employees at the same client company and a second record for one of those employees. This is a design example, not a customer case study or measured Stacksync result.
- Keep the two employees separate despite their shared company and email domain.
- Use person-level identifiers and corroborating evidence to review the suspected duplicate.
- Check activities, permissions and external references before an approved merge.
- Confirm that subsequent synchronization resolves the surviving contact without recreating the retired record.
Measure false merges, unresolved candidates and duplicate recreations against the firm’s own baseline. Report an improvement only after reviewing actual outcomes; a lower record count alone is not proof of cleaner data.

Conclusion: Clean Data Requires Continuous Attention
Eliminating duplicates when you sync CRM systems isn't a one-time project but an ongoing process. By implementing the preventive measures, detection methods, and resolution techniques outlined in this guide, you'll maintain clean customer data that enables accurate reporting, efficient operations, and superior customer experiences.
Remember these key principles:
- Prevention is less expensive than cleanup
- Consistent identification rules must span all systems
- Field normalization dramatically improves match rates
- Automation is essential for long-term success
Whether you build custom deduplication processes or implement a purpose-built solution like Stacksync, the investment in clean data delivers significant returns through improved operational efficiency and customer satisfaction.
Apply this in modular and prefab building supply and installation: commercial configuration and released design revision
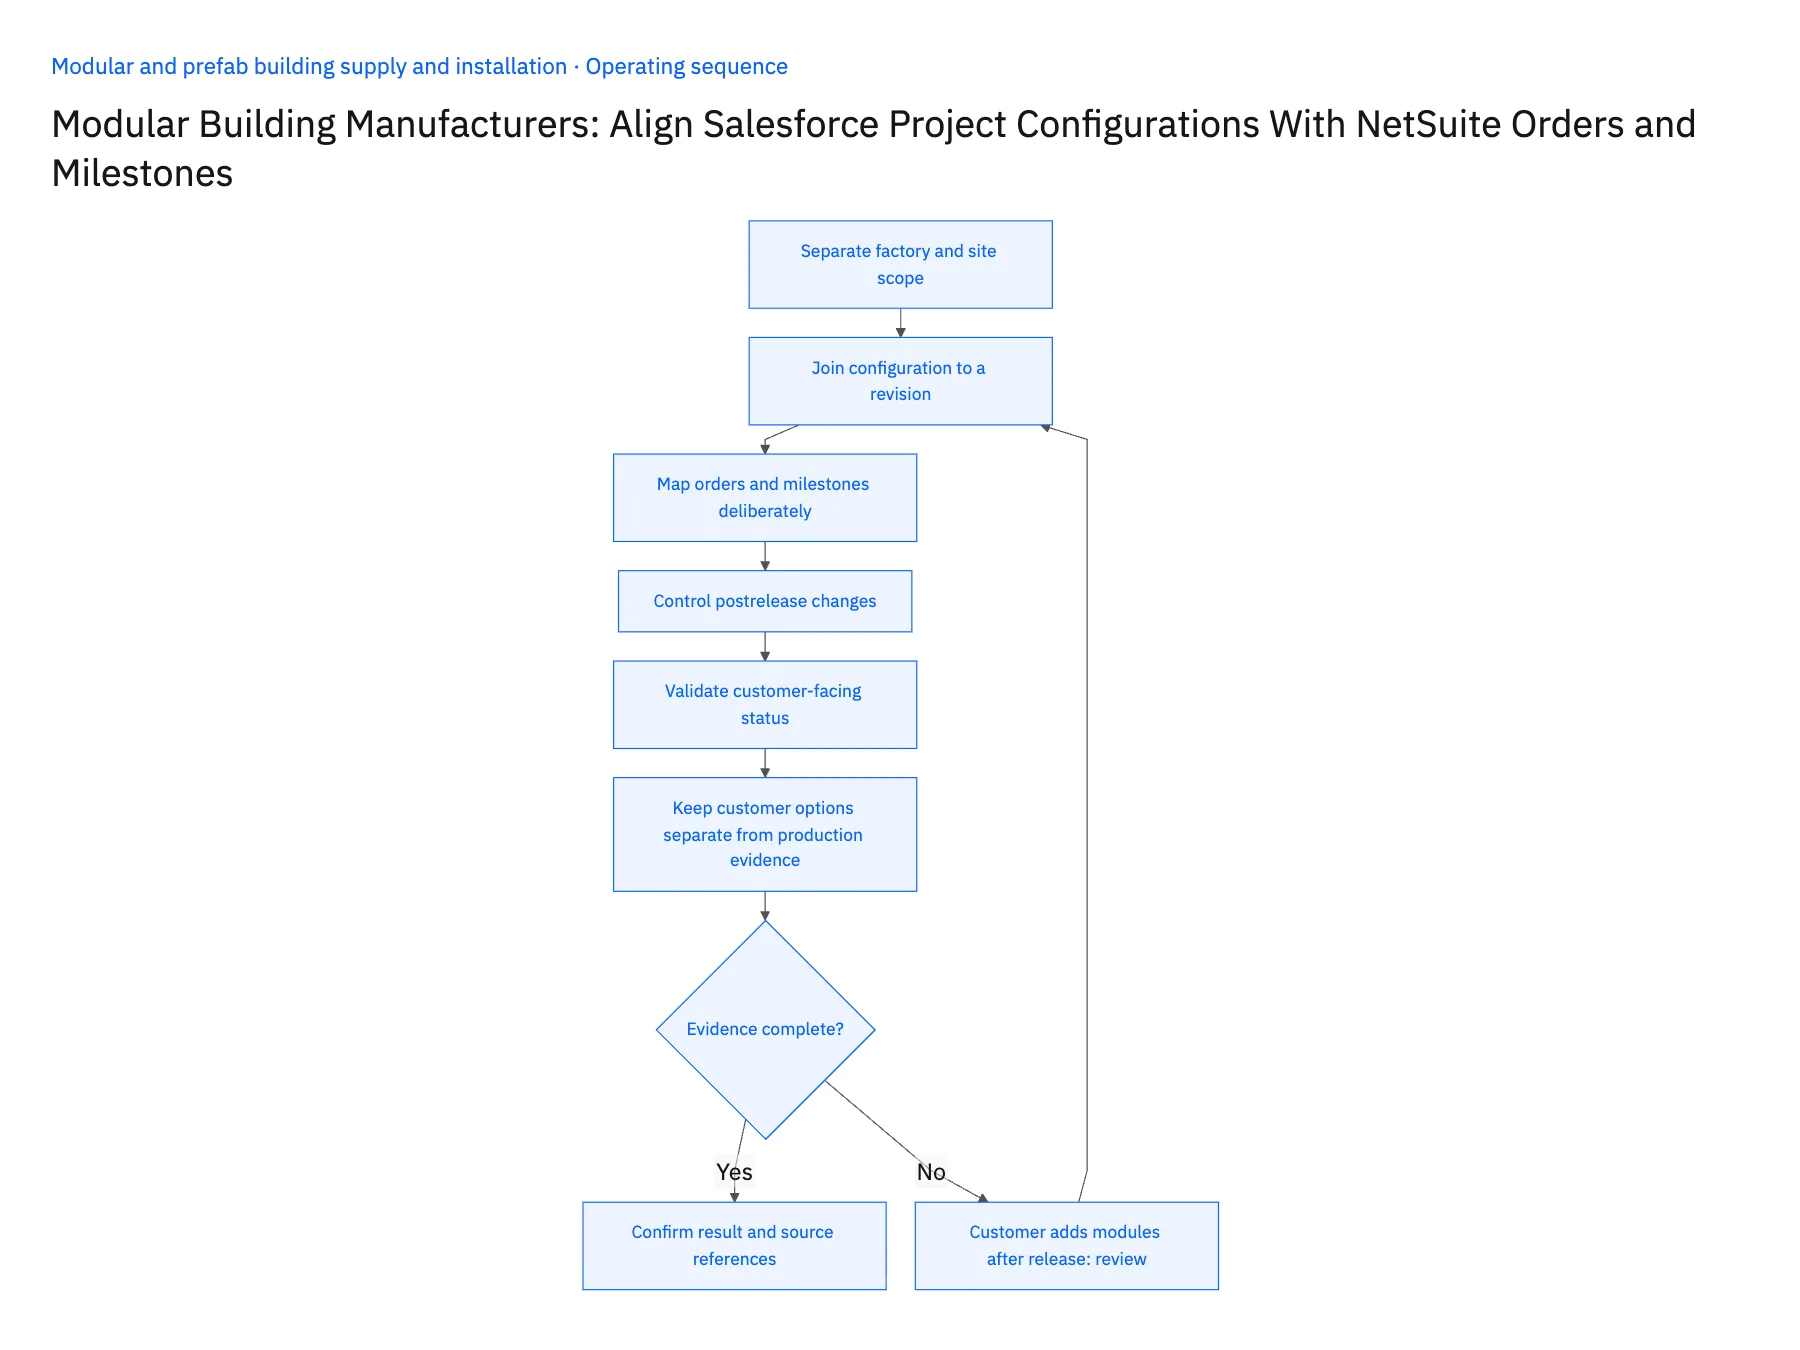
Modular projects may involve a dealer, contractor, owner, and billing entity with overlapping contact details. Apply the matching principles here before connecting Salesforce project configurations to NetSuite orders and milestones, keeping the distinct commercial roles intact.
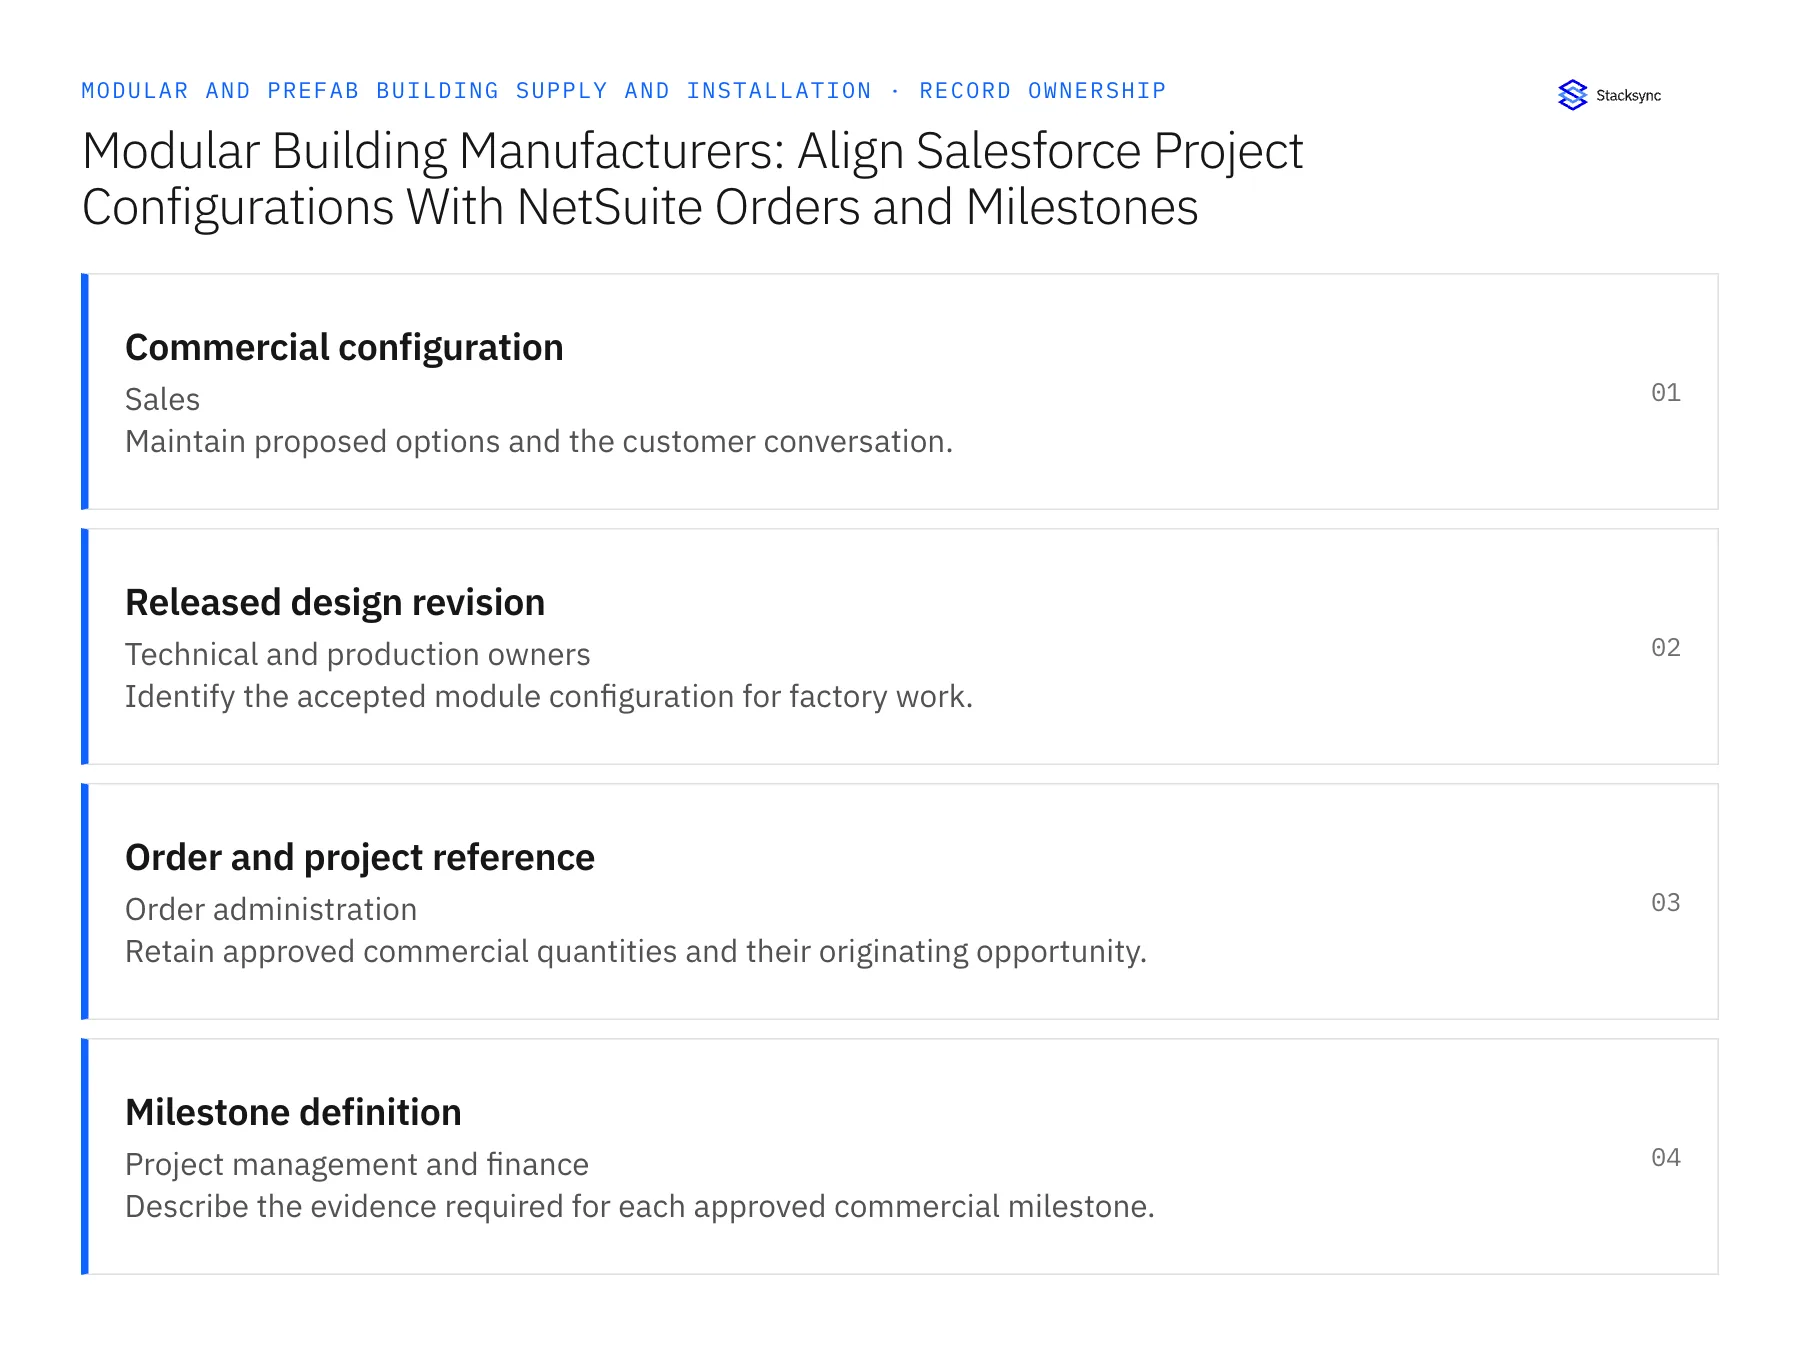
| Record to reconcile | Responsible owner | Rule to preserve |
|---|---|---|
| Commercial configuration | Sales | Maintain proposed options and the customer conversation. |
| Released design revision | Technical and production owners | Identify the accepted module configuration for factory work. |
| Order and project reference | Order administration | Retain approved commercial quantities and their originating opportunity. |
An exception to plan for: Customer adds modules after release. Create a reviewed scope revision with downstream impact rather than overwriting the original quantity. Acceptance check for the pilot: approved configuration identifies the released design revision.
The modular and prefab building supply and installation hub connects the broader operating context. These guides develop the specific record mappings and decisions for this application:
- Modular Building Manufacturers: Align Salesforce Project Configurations With NetSuite Orders and Milestones
- Salesforce–NetSuite for Modular Building Manufacturers
Ready to Eliminate CRM Duplicates?
Stacksync offers built-in duplicate prevention when synchronizing your CRM systems, maintaining clean data without extensive configuration or maintenance.
Request a demo to review stable record matching, retries, and your CRM’s approved duplicate-resolution process.
FAQ
Frequently asked questions



Explore these integrations and topics
Related articles